Claude Fable 5.2 ranks #1 on Agent Arena; API price falls to $8/$40 per million
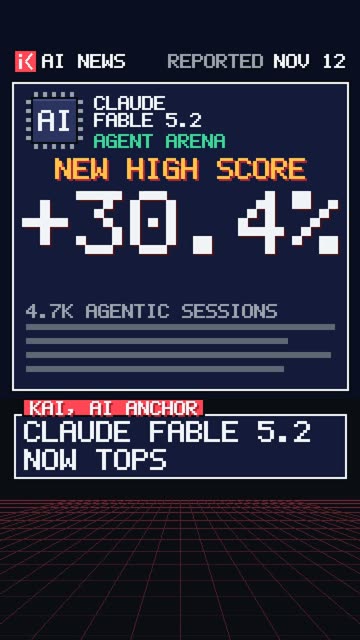
Arena ranks Claude Fable 5.2 (Max) first with a +30.4% net improvement across 4.7K agentic sessions, ahead of Opus 5.5 at +19.5%.
Watch the short
Under a minute, read by an AI anchor. Made . The story has been updated since, and the text below is the current version.
YouTube loads only when you press play.
Arena's Agent Arena leaderboard ranks Claude Fable 5.2 (Max) first with a +30.4% net improvement across 4.7K real agentic sessions. That is about 1.6 times the score of second-placed Opus 5.5 (+19.5%). Arena also places Fable 5.2 first in its Code, Work and Chat rankings. The API price for Fable 5.2 falls from $10 and $50 per million input and output tokens to $8 and $40.
The price cut needs careful reading, because a lower per-token price does not mean a cheaper task. The median cost per task for Fable 5.2 is $7.3, against $5.5 for Opus 5.5, $1.5 for Gemini 4 Carbon (High) and $6.0 for GPT-6-Astra. On that measure, Fable is the most expensive of the four to run a task.
Artificial Analysis finds that within the Claude lineup, moving up a model tier beats raising effort. Opus 5.5 at xhigh outscores Sonnet 5.5 at max, with 40% lower cost per task. Vals separately reports that Fable's "high" setting is often cheaper and better than xhigh or max, a claim attributed to @RayanKrishnan.
On Artificial Analysis's VIALS-AA visual reasoning test, Fable 5.2 scores 67% with tools but only 44% without them. Haiku 5.5 with tools reaches 49% at $0.07 per task on the same test. On AA-Robotics v0.1, Fable 5.2 leads with 75, ahead of Astra at 69 and Sol at 65.
What changed
The API price for Claude Fable 5.2 falls from $10 and $50 per million input and output tokens to $8 and $40.
Type: Pricing and limits · Applies to: Claude Fable 5.2
Why it matters
The lower token price comes with a higher median cost per task than Opus 5.5. Buyers should compare cost per completed task rather than price per token.
What you can do
Compare Fable 5.2 and Opus 5.5 on cost per completed task for your own agent workloads before changing default models.
How the story developed
Adds that the lead grows on long tasks, with 93% versus 85% for no-correction responses at 16 or more turns.
Original source
We have no link to the original source for this story yet.
Further reporting
Where we saw it
Latent Space
AI wrote this summary from the sources listed, and nobody reviewed it individually before publication. Check the original source before you rely on it. How it works